MotionMontage
Towards Controllable Cinematic
Human–Camera Motion Generation
Abstract
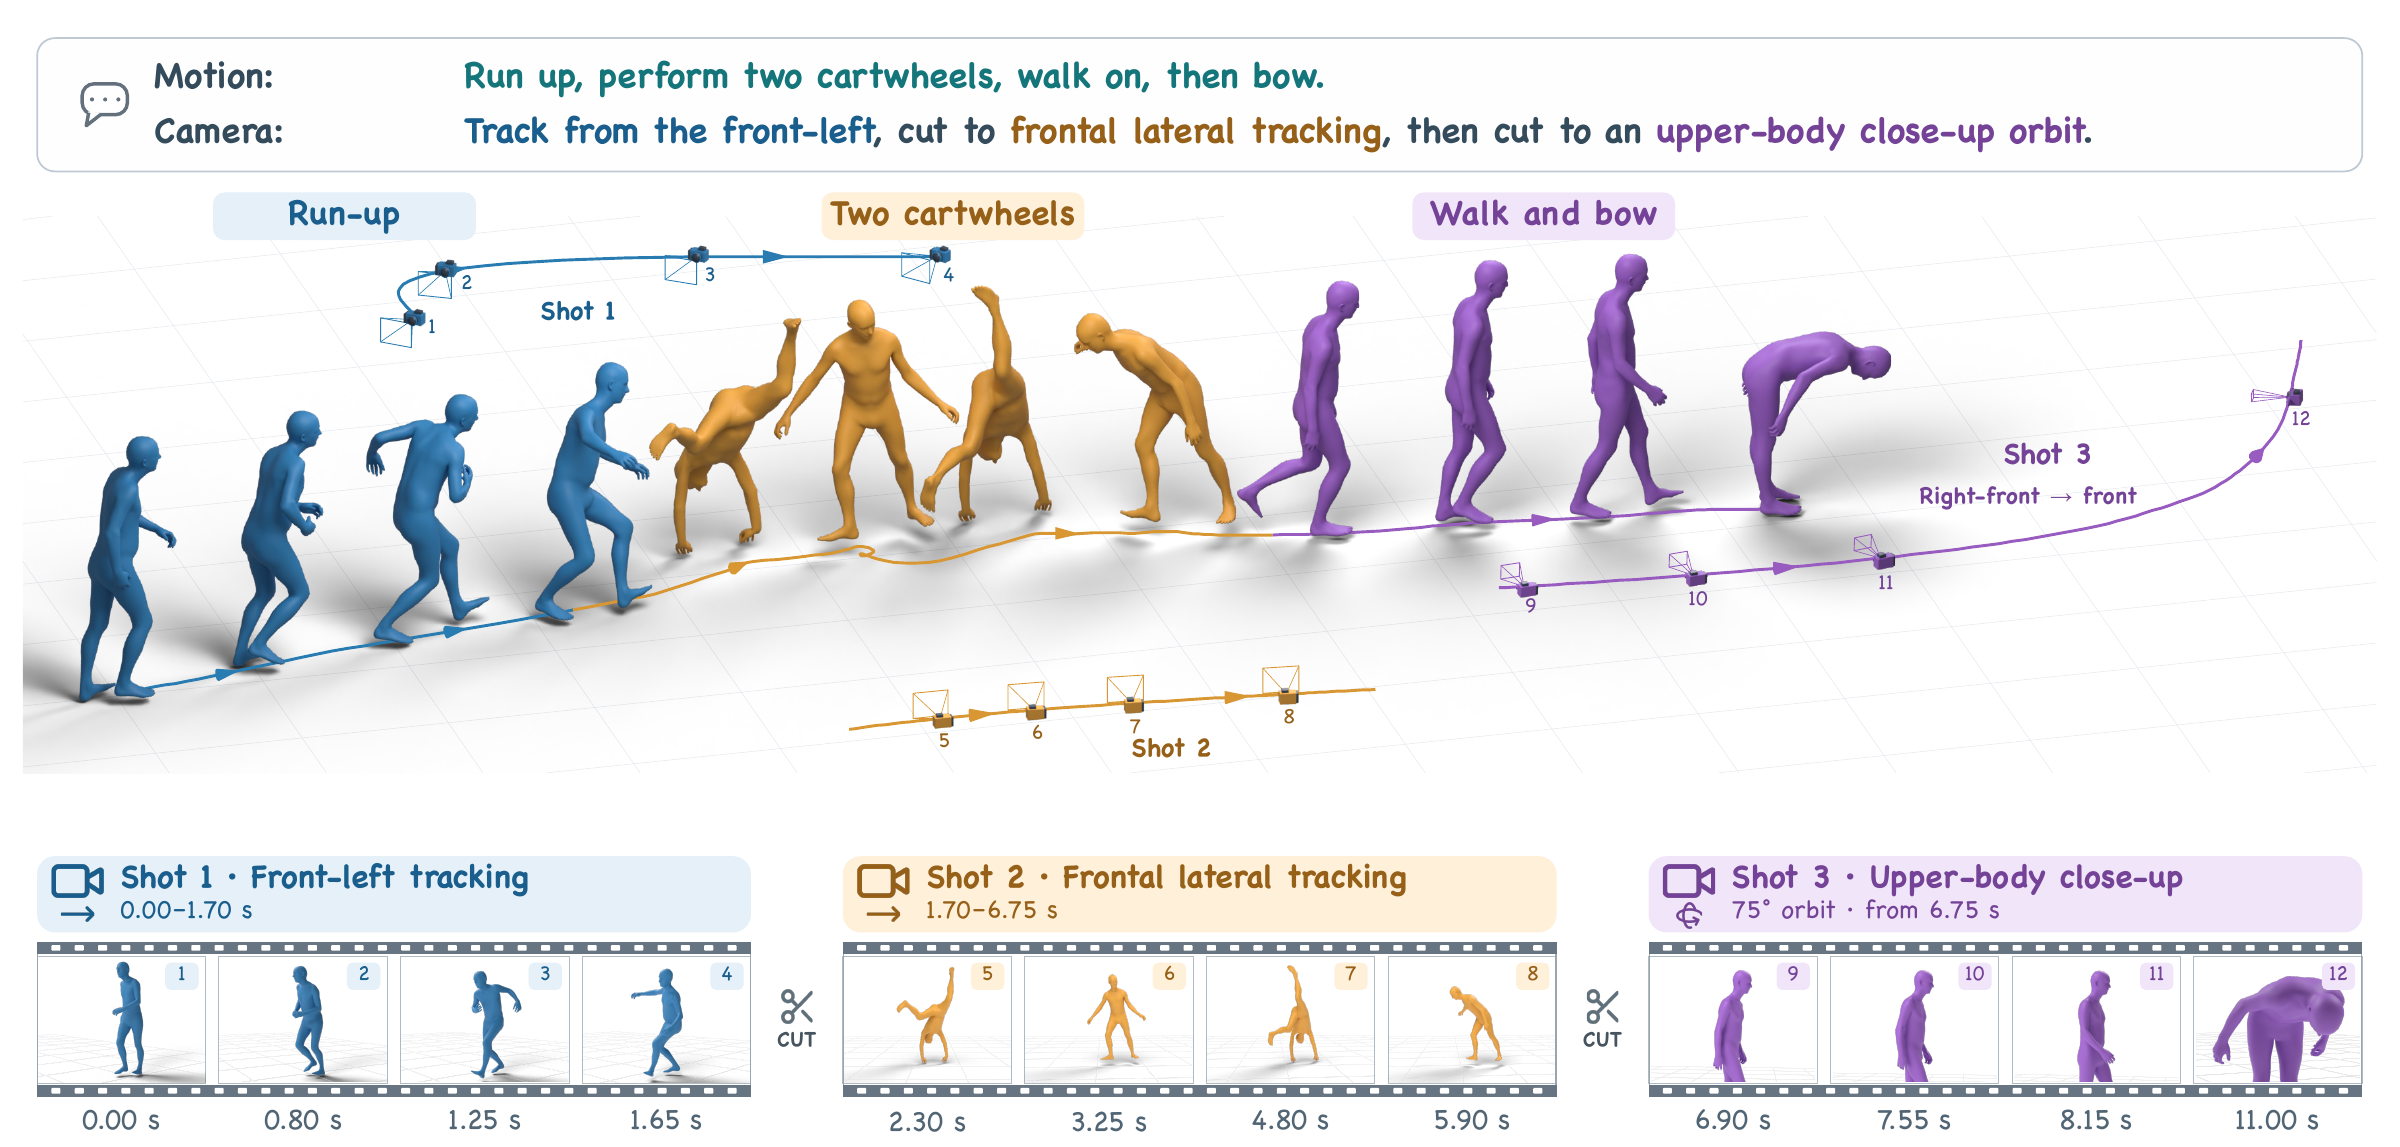
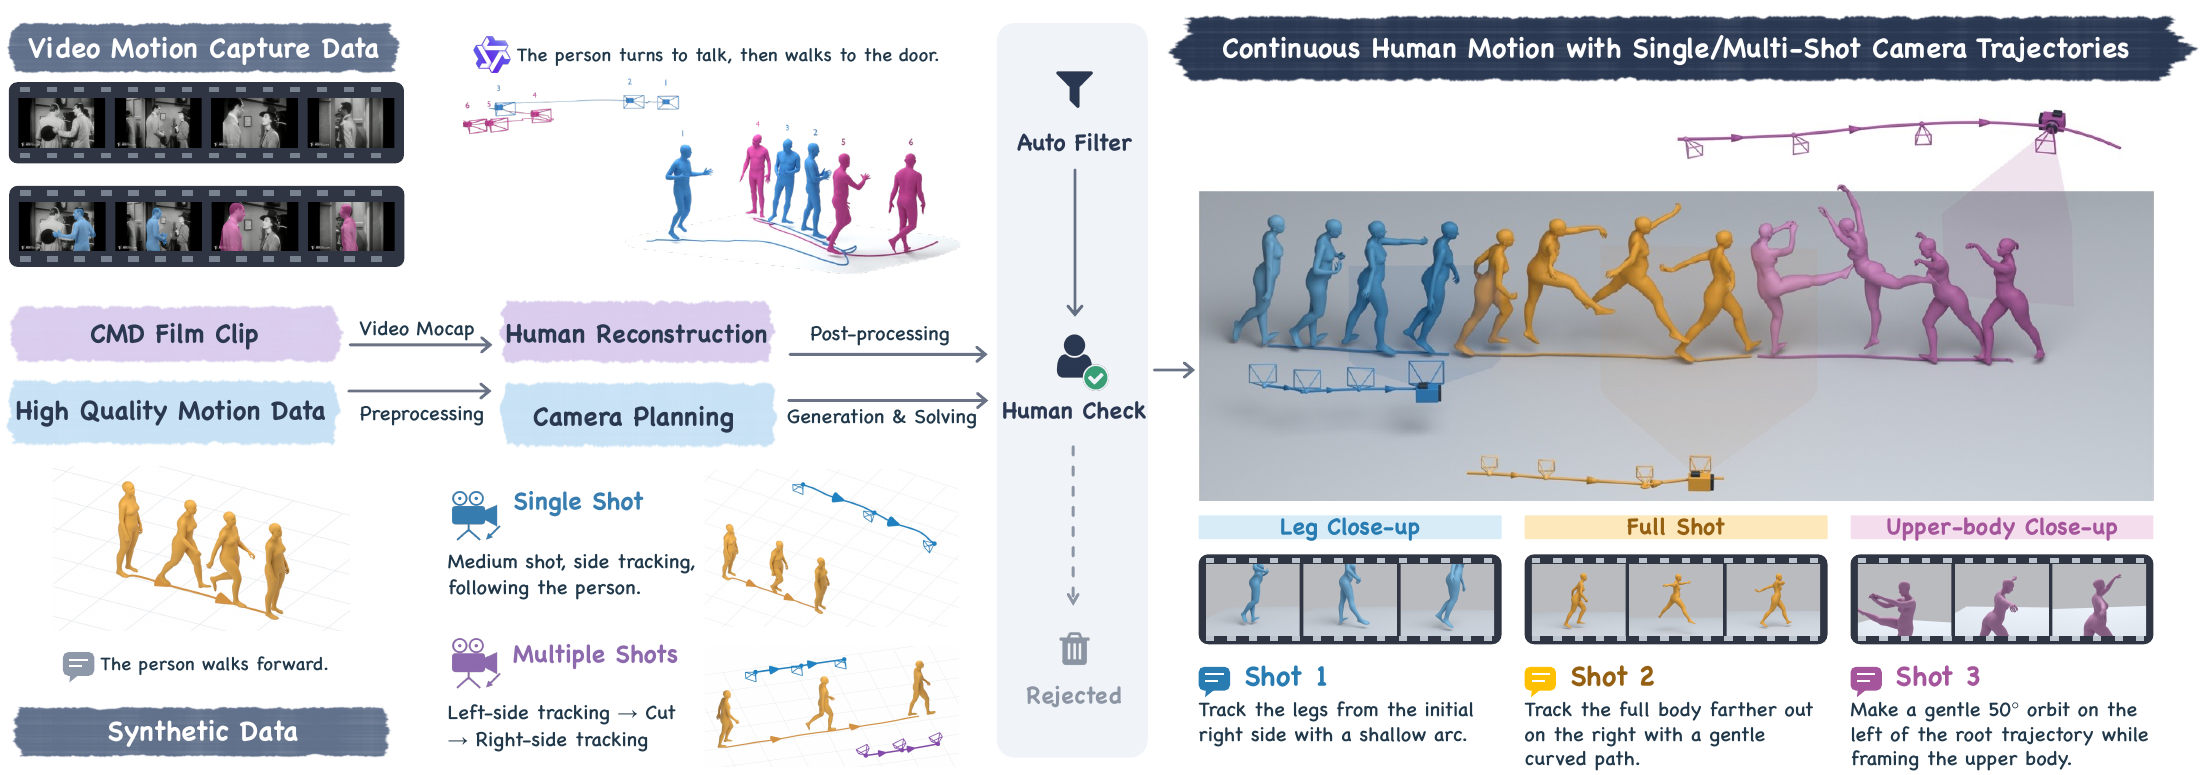
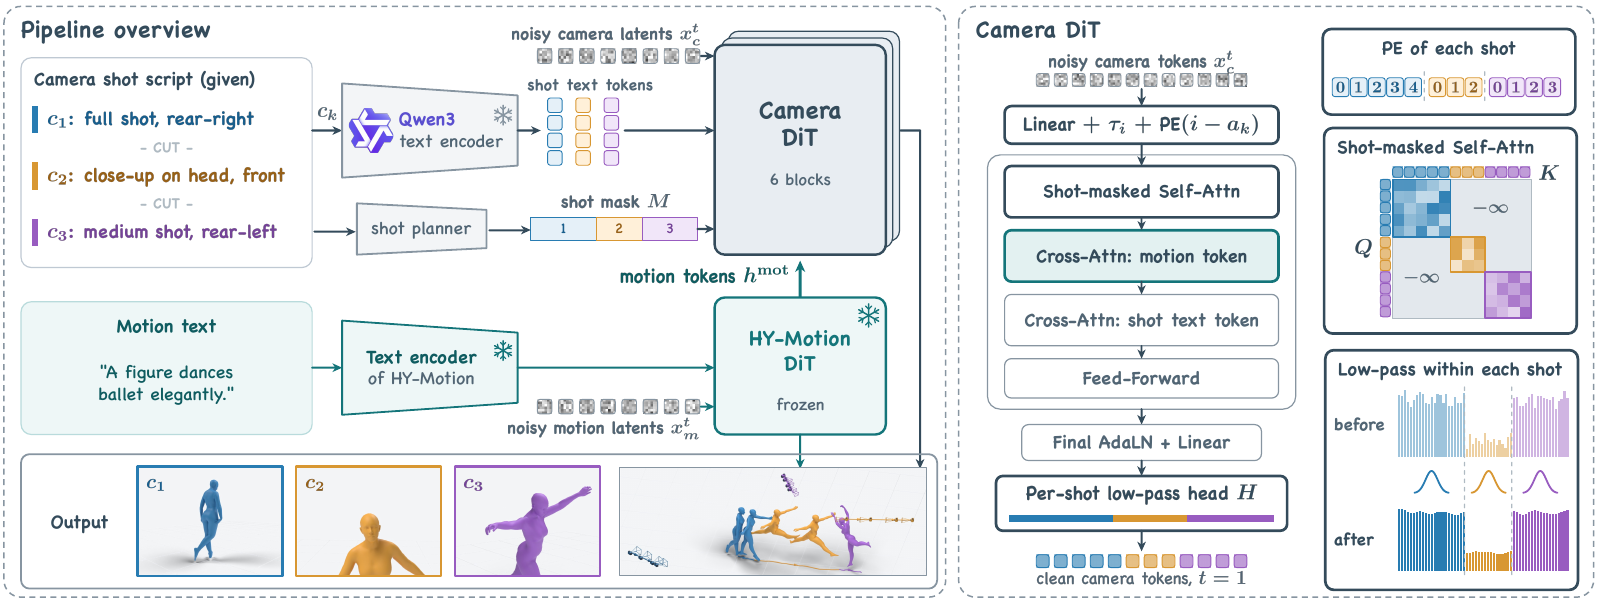
Cinematic 3D performances require tightly coupling human motion with camera movement, part-level close-ups, and mid-action shot cuts. However, existing text-driven methods mostly generate human motion or camera trajectories separately and are restricted to single-shot, full-body framing. To bridge this gap, we construct MotionMontage, a large-scale dataset of 269K human–camera sequences spanning 540 hours, featuring continuous camera movements, part-level close-ups, and multi-shot transitions. Combining procedural synthesis with 3D movie reconstructions, it pairs each sequence with geometry-grounded descriptions of both the action and cinematographic intent. Building on this dataset, we propose MontageDiT, a flow-matching diffusion transformer that jointly denoises 3D human motion and multi-shot camera trajectories on a shared time grid. By combining subject-centric coordinates, shot-masked attention, and image-space framing supervision, MontageDiT handles within-shot dynamics, part-level close-ups, and hard cuts in a single generation process. Experiments on joint and motion-conditioned generation demonstrate marked gains in trajectory realism, framing accuracy, and temporal smoothness.
01 / Dataset
MotionMontage Dataset
Dataset comparison
| Dataset | Camera | Human | Shot attributes | Scale | |||||
|---|---|---|---|---|---|---|---|---|---|
| Trajectory | Caption | Motion | Caption | Multi-shot | Close-up | Hours | Frames | Samples | |
| RealEstate10K | ✓ | ✕ | ✕ | ✕ | ✕ | ✕ | 121 | 11.0M | 79.0K |
| DynPose100K | ✓ | ✕ | ✕ | ✕ | ✕ | ✓ | 157 | 6.8M | 100.0K |
| CCD | ✓ | ✓ | ✕ | ✕ | ✕ | ✓ | 50 | 4.5M | 25.0K |
| DataDoP | ✓ | ✓ | ✕ | ✕ | ✕ | ✓ | 113 | 11.0M | 29.0K |
| KIT-ML | ✕ | ✕ | ✓ | ✓ | ✕ | ✕ | 12 | 0.8M | 4.0K |
| HumanML3D | ✕ | ✕ | ✓ | ✓ | ✕ | ✕ | 29 | 2.0M | 14.0K |
| Motion-X++ | ✓ | ✕ | ✓ | ✓ | ✕ | ✓ | 181 | 19.5M | 120.0K |
| E.T. | ✓ | ✓ | ✓ | ✕ | ✕ | ✓ | 120 | 11.0M | 115.0K |
| PulpMotion | ✓ | ✓ | ✓ | ✓ | ✕ | ✓ | 314 | 22.0M | 193.0K |
| Auteur | ✓ | ✓ | ✓ | ✓ | ✕ | ✓ | — | 2.7M | 34.0K |
| MovieShots | ✕ | ✕ | ✕ | ✕ | ✕ | ✓ | 51.4 | — | 46,857 |
| ShotVerse-Bench | ✓ | ✓ | ✕ | — | ✓ | ✓ | 31.3 | 12.0M | 20.5K |
| HoloCine | ✕ | ✓ | ✕ | ✓ | ✓ | — | — | — | 400.0K |
| MotionMontage | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | 539.8 | 42.0M | 269.4K |
✓ Documented presence ✕ Not provided — Unverified or unreported. Swipe to view all columns.
Dataset visualizations
Human Caption
Camera Caption
02 / Method
MontageDiT
03 / Results
Main comparison
| Method | Motion | Camera | Framing | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| FID ↓ | R@1 ↑ | R@2 ↑ | R@3 ↑ | MM-Dist ↓ | Div. → | FDCLaTr ↓ | CLaTr-S ↑ | Cov. ↑ | R@3 ↑ | FDFrm ↓ | Out ↓ | |
| Single-shot test set | ||||||||||||
| GT | 0.001 | 51.86 | 71.81 | 81.45 | 2.961 | 9.607 | 0 | 90.60 | 1.000 | 95.44 | 0 | 0.000 |
| DIRECTOR | — | — | — | — | — | — | 14.85 | 71.67 | 0.708 | 93.60 | 0.08 | 0.587 |
| MontageDiT* | — | — | — | — | — | — | 2.55 | 89.59 | 0.939 | 94.35 | 0.01 | 0.001 |
| PulpMotion | 2.724 | 28.29 | 44.26 | 55.04 | 4.551 | 8.342 | 53.09 | 77.99 | 0.530 | 94.10 | 70.03 | 4.768 |
| MontageDiT | 0.228 | 50.66 | 70.39 | 80.27 | 3.067 | 9.432 | 16.07 | 80.95 | 0.775 | 96.26 | 2.32 | 0.045 |
| Multi-shot test set | ||||||||||||
| GT | 0.001 | 50.39 | 69.96 | 79.99 | 3.017 | 9.534 | 0 | 81.94 | 1.000 | 71.26 | 0 | 0.022 |
| MontageDiT* | — | — | — | — | — | — | 3.82 | 81.33 | 0.906 | 73.35 | 0.13 | 0.101 |
| MontageDiT | 0.321 | 49.48 | 68.68 | 78.42 | 3.143 | 9.167 | 7.06 | 77.59 | 0.849 | 62.62 | 2.93 | 0.145 |
| Full test set | ||||||||||||
| GT | 0.001 | 51.57 | 71.53 | 81.31 | 2.973 | 9.613 | 0 | 87.10 | 1.000 | 87.29 | 0 | 0.006 |
| MontageDiT* | — | — | — | — | — | — | 2.28 | 86.26 | 0.924 | 87.38 | 0.06 | 0.026 |
| MontageDiT | 0.243 | 50.53 | 70.14 | 80.00 | 3.085 | 9.373 | 8.91 | 79.60 | 0.800 | 82.92 | 2.33 | 0.069 |
* Camera generation from ground-truth motion, compared with DIRECTOR; joint generation is compared with PulpMotion. Bold: best per pair. Camera R@3: CLaTr retrieval; FDFrm: FDFraming (×102); Out: out-of-frame rate (%); → closer to GT is better. Swipe to view all columns.